
Train a text classifier that knows when it isn't sure, and ship it with receipts.




LocalDesk turns a CSV or JSONL file and a JSON list of labels into a versioned, calibrated classification service that runs locally. It is built for routing: support tickets, intents, spam, triage queues. In those settings a confident wrong answer costs more than asking a human.
- Abstains instead of guessing. Every prediction is either
routeorreview, based on calibrated confidence and the margin between the top two labels. - Quality gates before deploy. A version that misses your accuracy, macro-F1, calibration or coverage thresholds cannot be promoted or served.
- Every version is reproducible and tamper-evident. Each version is immutable and pins the task, the data fingerprints, the report and the training plan with SHA-256 checksums.
- CPU first, LLM when it pays off. The default TF-IDF model trains in seconds, reaches 91–99% accuracy on three of four public benchmarks, and needs only the Python standard library for inference. An optional Qwen + Unsloth LoRA recipe gave a further +5.7 pp accuracy on the hardest one, real IT tickets.
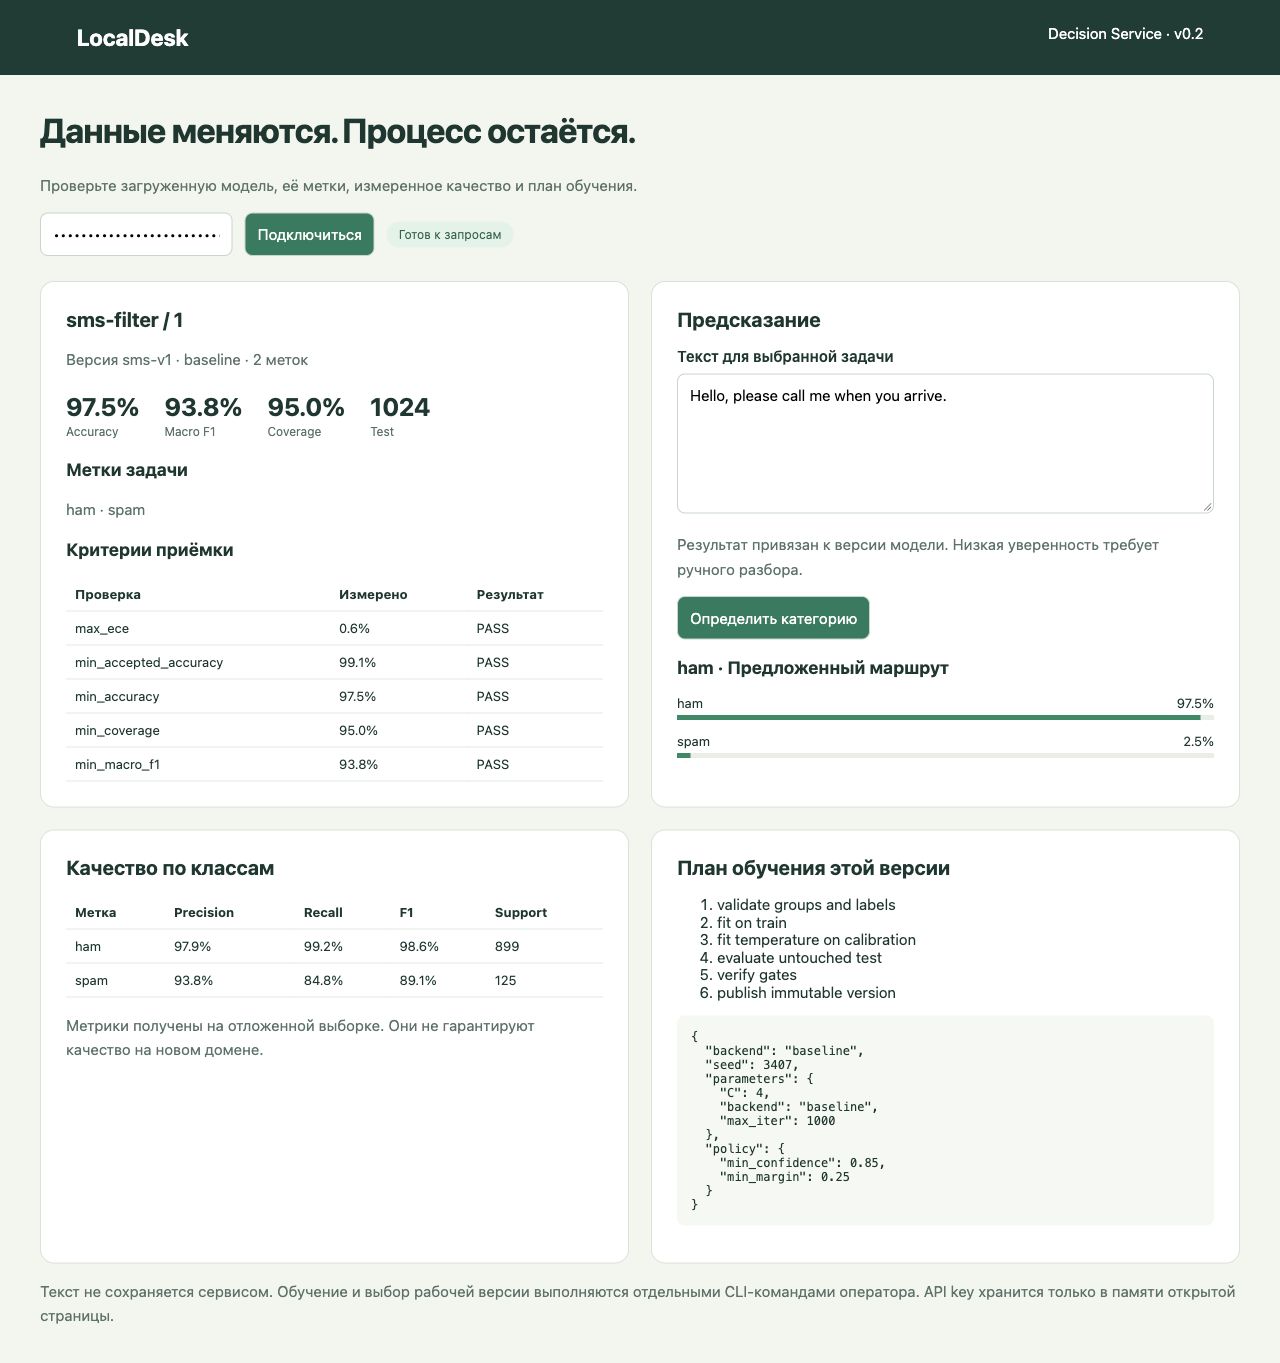
The package ships with the TF-IDF demo model trained on real IT tickets (76.5% accuracy on the 524-ticket holdout, report). Running a prediction has no runtime dependencies:
pip install localdesk
localdesk predict "File share access request"
localdesk predict "I can't open the shared finance folder"
A clear request is routed. An ambiguous one goes to a human with the reason attached (output abbreviated):
Run localdesk serve to open the same model in a local web page at http://127.0.0.1:8765.
1. Describe the task. The labels are yours; nothing in the core is IT-specific.
{
"id": "my-intents",
"version": "1",
"instructions": "Choose the intent of the message.",
"labels": {
"returns": "Requests to return a purchased item.",
"delivery": "Questions or problems with delivery.",
"other": "Other supported customer requests."
},
"min_confidence": 0.8,
"min_margin": 0.2
}2. Point an experiment at your file and set the bar a model must clear.
{
"task": "my-task.json",
"dataset": {
"path": "my-records.csv",
"format": "csv",
"text_column": "message",
"label_column": "intent",
"id_column": "id"
},
"registry": "my-registry",
"training": {"backend": "tfidf"},
"gates": {"min_accuracy": 0.7, "min_macro_f1": 0.6, "max_ece": 0.1}
}3. Validate, train, promote, serve.
pip install 'localdesk[baseline,service]' # training + HTTP API
localdesk validate my-experiment.json # checks labels, leakage, class support
localdesk train my-experiment.json --run-id v1 # fit, calibrate, evaluate, gate
localdesk runs --registry my-registry # list versions and gate results
localdesk promote v1 --registry my-registry # refuses versions that failed gates
localdesk api --registry my-registry --anonymous-localPaths are relative to the experiment file. JSONL supports dotted fields such as
gold.category, and you can supply explicit train/calibration/test files.
Unknown labels, conflicting duplicates, groups that cross splits and typos in the
configuration fail early with a clear message.
The same pipeline and commands on four public datasets. Only the configuration changes.
Default tfidf backend, test sets never used for fitting or calibration:
| Dataset | Labels | Test rows | Accuracy | Macro F1 | Auto-routed | Accuracy when routed |
|---|---|---|---|---|---|---|
| IT Support Tickets | 6 | 524 | 76.5% | 72.9% | 60.5% | 92.4% |
| UCI SMS Spam | 2 | 1,024 | 98.9% | 97.4% | 97.7% | 99.3% |
| Banking77 | 77 | 3,071 | 91.2% | 91.3% | 86.9% | 96.8% |
| CLINC150 | 150 | 4,486 | 92.3% | 92.2% | 88.9% | 97.0% |
"Auto-routed" is the share of requests the model handled without a human under the task's fixed review policy, and "Accuracy when routed" is measured on those requests only. Compared with the legacy hashed baseline, TF-IDF adds 1.5–7.1 pp accuracy on every dataset and routes 2.6–16.4 pp more requests automatically (full comparison). Training takes 1–40 seconds on a laptop CPU.
The gain holds across seeds: re-splitting train and calibration five times with the test sets fixed, TF-IDF beats the baseline on every dataset for every seed, by +1.0 to +9.0 pp accuracy; the standard deviation of its accuracy is at most 0.9 pp (seed report).
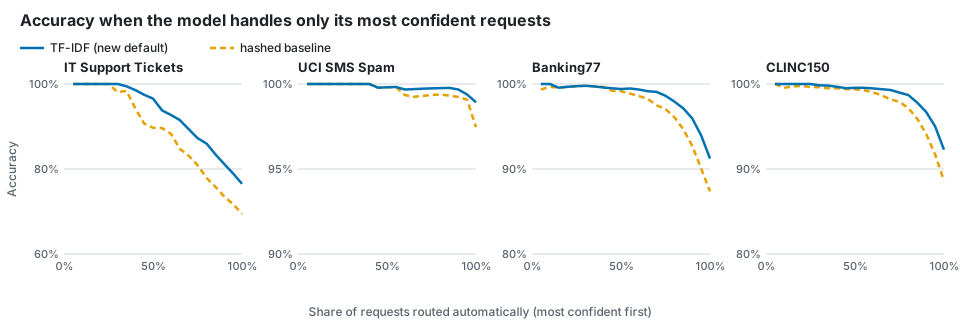
The fewer requests the model takes, the more accurate it gets. On Banking77, TF-IDF keeps 95% accuracy on its most confident 93% of queries; the old baseline holds that accuracy on only 84%. These curves are read off the test sets: use them to choose a policy, then confirm it on your own data.
Queries outside every label. CLINC150 includes 1,000 test queries that match none of its 150 intents and are never seen in training. Under the default policy, about 84% of them go to human review (83.6 ± 1.4% over five seeds) instead of receiving a wrong intent.
To reproduce from a clone of this repository (the scripts download and checksum the public data):
pip install -e '.[baseline]'
python scripts/prepare_data.py && python scripts/prepare_sms.py
python scripts/prepare_banking77.py && python scripts/prepare_clinc150.py
python scripts/publish_cpu_suite.py # both CPU backends on all four datasetsFine-tuned Qwen vs classic baselines (same 524 IT test rows, free Colab T4):
| Method | Accuracy | Macro F1 | p50 latency |
|---|---|---|---|
| Qwen 3.5 4B + LoRA (LocalDesk recipe) | 82.8% | 80.6% | 389 ms |
| TF-IDF + SVM (tuned) | 77.1% | 73.5% | 1.8 ms |
| TF-IDF + logistic regression | 77.7% | 74.0% | 2.1 ms |
| Qwen 3.5 4B zero-shot | 55.3% | 54.1% | 251 ms |
The accuracy gain over the SVM is +5.73 pp, with a paired-bootstrap 95% CI of [+2.48, +9.16] pp. Macro-F1 gain is +7.06 pp, with a 95% CI of [+3.31, +11.10] pp. Full protocol: docs/BENCHMARK.md · report: reports/comparison-colab-it.md · run it yourself: Colab notebook.
These are reused public holdouts, not a field trial. Measure on your own data before relying on the numbers. docs/VALIDATION.md lists exactly what was and wasn't verified.
flowchart LR
C[Task + experiment JSON] --> D[CSV / JSONL intake]
D --> V[Validate labels, group duplicates, isolate splits]
V --> T[Train: CPU TF-IDF or Qwen LoRA]
T --> K[Calibrate on a separate split]
K --> E[Evaluate on untouched test]
E --> G{Quality gates}
G -->|pass| R[Immutable version in registry]
G -->|fail| X[Kept for inspection, never served]
R --> P[promote / rollback]
P --> A[HTTP API + dashboard]
- No leakage by construction. Records that share a conversation or produce identical model features are grouped together, and a group never spans train/calibration/test.
- Training and serving are separate processes. The HTTP API cannot upload data, train or promote; it only answers predictions. Operators use the CLI.
- Promotion is an atomic pointer swap. Rollback is
localdesk promote <older-run>. Workers verify every checksum on startup.
More detail: architecture and contracts · training plan.
A ready image with the IT-tickets demo model is published to GitHub Container Registry
for linux/amd64 and linux/arm64:
docker run --rm -p 127.0.0.1:8765:8765 -e LOCALDESK_API_KEY=change-me \
ghcr.io/denis-samatov/localdeskOpen http://127.0.0.1:8765, paste the key and click Connect. The dashboard is
in English with a Russian toggle (or ?lang=ru). To serve your own trained and
promoted versions, mount a registry over the demo: -v "$PWD/my-registry:/models:ro".
export LOCALDESK_API_KEY=change-me
localdesk api --registry my-registry # or: docker compose up --build -d
curl http://127.0.0.1:8765/v1/predictions \
-H "X-API-Key: $LOCALDESK_API_KEY" -H 'Content-Type: application/json' \
-d '{"text": "Where is my parcel?"}'| Endpoint | Purpose |
|---|---|
POST /v1/predictions, POST /v1/predictions/batch |
Decision, probabilities, model version and task hash |
GET /v1/model, /v1/model/report, /v1/model/plan |
Active labels, measured quality, gates and training plan |
GET /health/live, /health/ready |
Liveness; readiness only when a qualified model is loaded |
GET /metrics |
Prometheus counters (no request bodies are logged) |
Inference requests are queued and run one at a time, so a single process can safely hold a GPU model. The API key is compared in constant time, bodies are size- and time-limited, and anonymous mode accepts only loopback hosts and origins. The Docker setup runs as a non-root user with a read-only filesystem and models mounted read-only. See the runbook. The local CPU pilot provides a frozen public-data HTTP/load/restart/backup/restore/rollback drill with explicit scope and evidence.
Swap the training block and keep the rest of the pipeline:
"training": {"backend": "unsloth", "epochs": 2, "rank": 16, "batch_size": 2,
"gradient_accumulation": 4, "learning_rate": 0.0002}The classification head is built from your label descriptions. Upstream
revisions are pinned in requirements-gpu.txt. Training stops on skipped or
truncated examples instead of silently degrading. Setup: docs/TRAINING.md.
GPU serving details: docs/GPU_HTTP.md.
LocalDesk is v0.3, early but tested. CI runs lint, formatting, the test suite, package build and a CLI smoke test on Linux, macOS and Windows with Python 3.11, 3.12 and 3.13.
Current scope is single-label text classification on a single node. Not included yet: multi-label targets, a hosted Qwen checkpoint you can download, multi-tenant isolation, and hot-swapping models without a restart.
git clone https://github.com/denis-samatov/localdesk.git && cd localdesk
uv sync --frozen --extra dev --extra baseline --extra service
uv run pytest -q
uv run ruff check . && uv run ruff format --check .Issues and pull requests are welcome. Please include a test for any change in behaviour.
Architecture · Runbook & API · Datasets & provenance · Training · Benchmark protocol · GPU HTTP check · Validation evidence
LocalDesk превращает CSV/JSONL и список меток в калиброванный сервис классификации текста с версиями и порогами качества. Модель отвечает «маршрутизировать» или «на ручной разбор», если не уверена. Ядро не привязано к домену: меняются только JSON-описание задачи и датасет. Обучение на CPU занимает секунды. Дообучение Qwen через Unsloth дало +5,7 п.п. точности к сильному TF-IDF baseline на реальных IT-заявках. На четырёх публичных датасетах (IT-заявки, SMS, Banking77, CLINC150) CPU-модель по умолчанию даёт от 76,5% до 98,9% точности, а около 84% запросов вне всех категорий отправляет на ручной разбор. Качество на других языках и в других организациях нужно измерять отдельно.
Code and notebooks: MIT. The bundled demo model and benchmarks use public datasets under CC BY 4.0; attribution is in NOTICE.md. Optional dependencies and model weights keep their own licenses.
{"category": "Fileservice", "action": "route",  "probabilities": {"Fileservice": 0.999, ...}, "review_reasons": []}
{"category": "Fileservice", "action": "review", "probabilities": {"Fileservice": 0.43, "Support general": 0.24, ...},
 "review_reasons": ["low_confidence", "small_margin"]}